Traditional software development relies on explicit instructions. An engineer writes deterministic code: IF customer_type == "enterprise" THEN apply_discount(0.20). While this approach works well for structured business logic, it breaks down when applied to complex, unstructured problems like voice recognition, fraud detection, or medical diagnosis. You cannot manually code an IF/ELSE rule for every possible variation of a human voice accent or a fraudulent bank transaction.
Machine Learning (ML) fundamentally flips this paradigm. Instead of hand-coding rules, engineers feed algorithms historical data alongside target outputs. The machine learns the underlying statistical patterns autonomously, constructing a mathematical model capable of making predictions on unseen future data.
In this comprehensive beginner’s guide, we demystify machine learning from the ground up: how it works under the hood, the core learning paradigms, essential real-world applications, and the modern tooling stack powering production ML in 2026.
1. Traditional Programming vs. Machine Learning Paradigm
To grasp why machine learning is transformative, consider the fundamental difference in how inputs and outputs are processed compared to legacy software architecture.
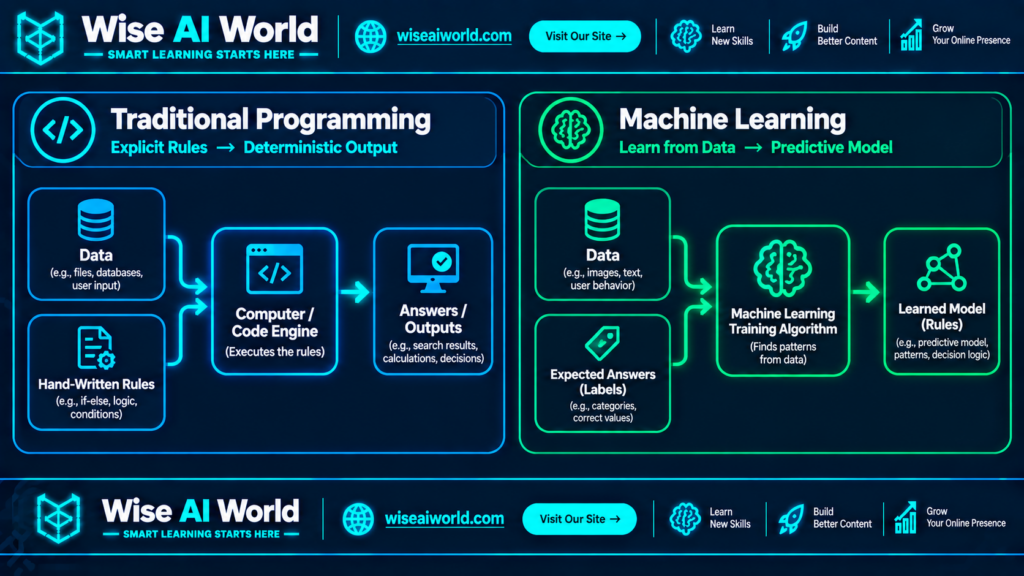
The Two Architectural Pipelines
- Traditional Paradigm: Inputs (Data) + Hand-Written Logic (Rules) → Program Execution → Answers.
- Machine Learning Paradigm: Inputs (Data) + Expected Outcomes (Answers/Labels) → Training Algorithm → Model (Learned Rules & Weights).
Once an ML model is trained, it transitions to the Inference Phase, where it evaluates new, unlabelled data inputs and returns predictions with a calculated probability or confidence score.
2. The 3 Primary Machine Learning Paradigms
Machine learning techniques are broadly categorized into three core paradigms based on how the algorithm receives feedback during training.
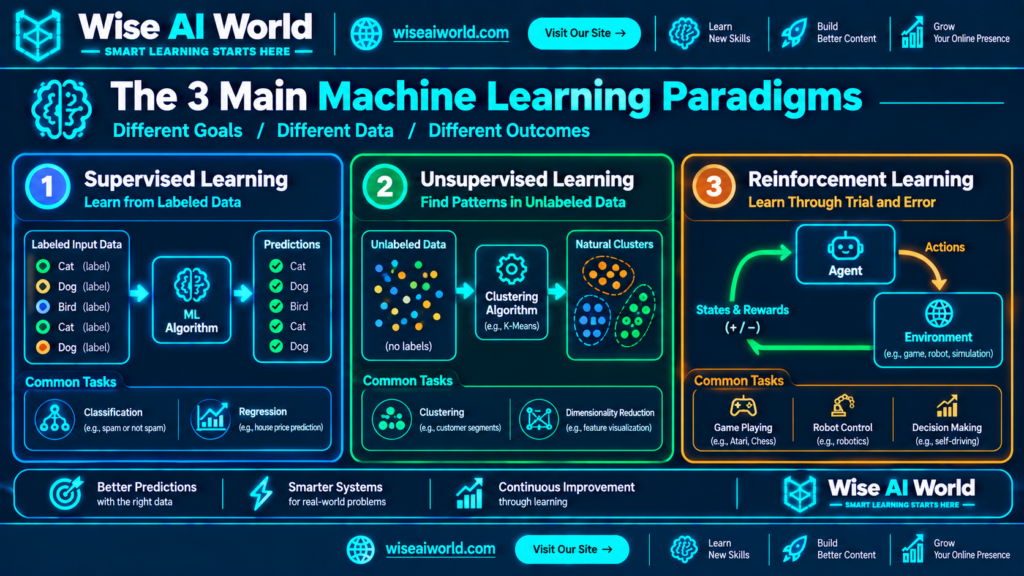
| Learning Paradigm | Data Input Type | Core Objective | Common Algorithms |
|---|---|---|---|
| Supervised Learning | Labeled datasets (Input X paired with Target Label Y) | Predict labels for new, unseen inputs (Classification & Regression). | Linear Regression, Logistic Regression, XGBoost, Random Forests. |
| Unsupervised Learning | Unlabeled datasets (Raw, un-categorized features) | Discover hidden structures, groupings, or clusters in data. | K-Means Clustering, PCA (Principal Component Analysis), DBSCAN. |
| Reinforcement Learning (RL) | Dynamic environmental feedback (States, Actions, Rewards) | Maximize cumulative reward through trial-and-error interaction. | Q-Learning, PPO (Proximal Policy Optimization), Deep Q-Networks (DQN). |
A. Supervised Learning: Predicting Known Outcomes
Supervised learning acts like a student studying with an answer key. The algorithm processes thousands of examples containing features (e.g., house square footage, neighborhood, number of bedrooms) alongside ground-truth labels (actual sale price). The model minimizes error by iteratively adjusting internal mathematical parameters (weights and biases).
B. Unsupervised Learning: Finding Hidden Patterns
In unsupervised learning, no answer keys or labels are provided. The model analyzes raw data points to find natural mathematical groupings or anomalies. For example, e-commerce platforms use unsupervised clustering to automatically group millions of shoppers into behavioral personas based on browsing history and cart additions.
C. Reinforcement Learning: Mastering Environments
Reinforcement learning trains autonomous agents to navigate complex environments. The agent receives positive reinforcement rewards for optimal choices and negative penalties for mistakes. This approach powers robotics control, algorithmic trading strategies, and game-playing systems like AlphaGo.
3. Step-by-Step Machine Learning Lifecycle
Deploying machine learning to production involves a repeatable six-stage engineering lifecycle known as Machine Learning Operations (MLOps).
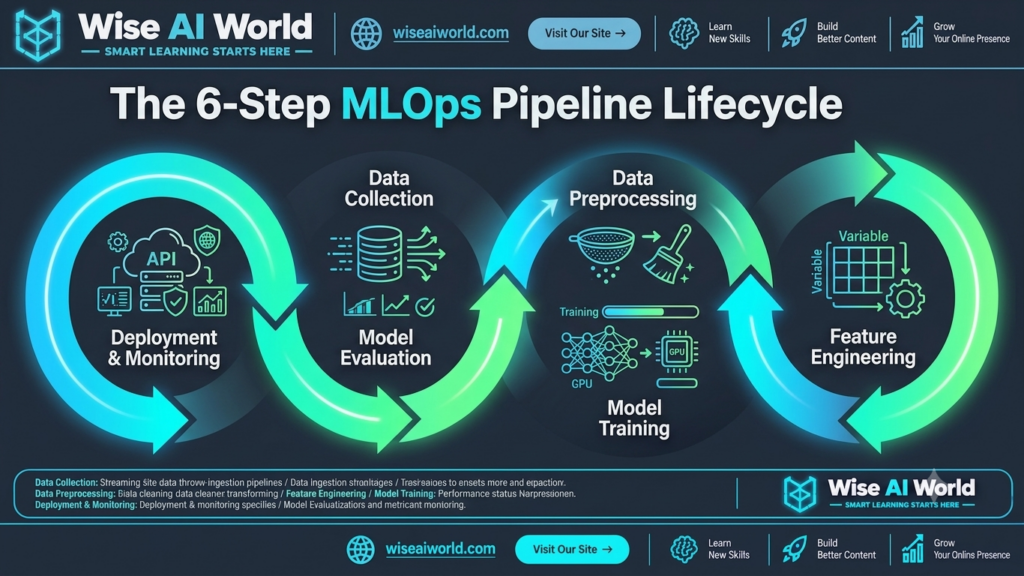
The 6 Stages of Model Development
- Data Collection & Ingestion: Gathering structured tabular data, unstructured text, or images from databases, APIs, or data lakes.
- Data Cleaning & Preprocessing: Removing duplicate records, imputing missing values, and scaling numeric features uniformly.
- Feature Engineering: Extracting meaningful numerical variables (e.g., converting timestamp strings into “day_of_week” or “is_weekend” binary flags).
- Model Training & Hyperparameter Tuning: Passing training splits into algorithms and tuning hyperparameters to optimize accuracy without overfitting.
- Validation & Testing: Evaluating performance against an un-seen holdout test set using metrics like Accuracy, Precision, Recall, and F1-Score.
- Deployment & Monitoring: Wrapping the trained weights into a web endpoint (FastAPI/REST) and monitoring for model drift over time.
4. Practical Code Walkthrough: Housing Price Prediction in Python
To see machine learning in practice, here is a complete Python script using the industry-standard scikit-learn library. This snippet trains a Linear Regression model to predict house values based on square footage and age.
import numpy as np
from sklearn.model_selection import train_test_split
from sklearn.linear_model import LinearRegression
from sklearn.metrics import mean_squared_error, r2_score

# Step 1: Prepare Synthetic Real Estate Dataset
# Features [Square Footage, Age of House in Years]
X = np.array([
    [1200, 15], [1500, 10], [1800, 8], [2200, 5],
    [2500, 2],  [900, 25],  [1100, 20], [3000, 1]
])

# Target Variable [Actual Sale Price in USD]
y = np.array([250000, 310000, 360000, 450000, 520000, 180000, 220000, 610000])

# Step 2: Split Data into Training (75%) and Testing (25%) Sets
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.25, random_state=42)

# Step 3: Initialize and Train the Machine Learning Model
model = LinearRegression()
model.fit(X_train, y_train)

# Step 4: Evaluate Model Performance on Holdout Test Data
predictions = model.predict(X_test)
r2 = r2_score(y_test, predictions)

print(f"Model Training Complete.")
print(f"R-Squared Evaluation Score: {r2:.4f}")

# Step 5: Make Inference on a New House Listing [2,000 sq ft, 4 years old]
new_house = np.array([[2000, 4]])
predicted_price = model.predict(new_house)
print(f"Predicted Price for 2,000 sq ft house: ${predicted_price[0]:,.2f}")
5. Critical Challenges & Trade-offs in Machine Learning
Building effective machine learning models requires balancing key engineering trade-offs.
- Overfitting vs. Underfitting: An overfitted model memorizes the training data completely (including noise), resulting in terrible performance on new inputs. An underfitted model is too simple to capture real underlying trends.
- Data Quality & Bias: Models inherit biases present in their training datasets. Inaccurate or historically skewed data produces skewed predictions.
- Interpretability vs. Accuracy: Simple models like Decision Trees are easy to interpret (“black-box” transparent), whereas complex Deep Neural Networks yield higher accuracy but offer little visibility into how individual decisions are calculated.
6. Summary & Machine Learning Tooling Stack
Machine learning serves as the foundational mathematical engine behind modern software, driving advances across computer vision, natural language processing, and automated decision engines.
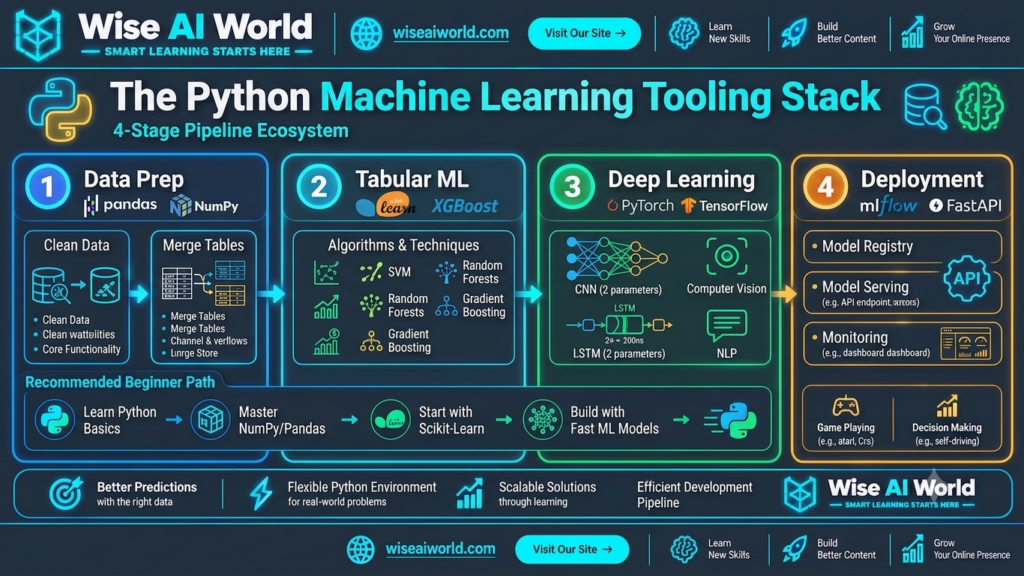
Recommended Beginner Path:
- Master Core Python: Gain confidence with
NumPyfor numerical calculations andPandasfor tabular data manipulation. - Learn Classic Algorithms: Master regression, classification trees, and clustering using
scikit-learnbefore diving into neural networks. - Practice on Real Datasets: Work on open community datasets (e.g., Kaggle) to practice data cleaning, feature engineering, and cross-validation firsthand.

Manish Prakash Dubey is an AI educator and technology writer based in India. He founded WiseAIWorld to make artificial intelligence simple and practical for students, professionals, and beginners. His work focuses on AI basics, machine learning, deep learning, NLP, computer vision, and real-world AI tools.
