Human language is wonderfully complex. It is filled with idioms, sarcasm, double meanings, grammar variations, slang, and cultural context. While humans learn to comprehend and speak language effortlessly from childhood, teaching a computer—which operates strictly on binary math and rigid logic—to understand human text was long considered one of the hardest challenges in computer science.
Enter Natural Language Processing (NLP). NLP is the specialized branch of Artificial Intelligence (AI) that bridges the gap between human communication and computational understanding. It is the underlying technology that enables search engines to comprehend intent, translation apps to bridge languages, spam filters to clean inbox feeds, and Large Language Models (LLMs) like ChatGPT, Claude, and Llama 3 to hold human-like conversations.
In this beginner-friendly yet technically thorough guide, we break down what NLP is, how raw text is converted into numbers, the essential steps of text preprocessing, and how modern Transformer neural networks process human language.
1. What Is Natural Language Processing (NLP)?
At its core, Natural Language Processing combines computational linguistics (rule-based modeling of human language) with machine learning and deep learning models. The goal is to build software capable of reading, deciphering, understanding, and generating human languages in a valuable way.
NLP operates across two major functional branches:
- Natural Language Understanding (NLU): Focuses on machine comprehension—extracting intent, sentiment, entity references, and context from human text or speech inputs.
- Natural Language Generation (NLG): Focuses on machine output—producing coherent, contextually accurate human language text or speech from structured mathematical representations.
2. How Computers Read Text: The Preprocessing Pipeline
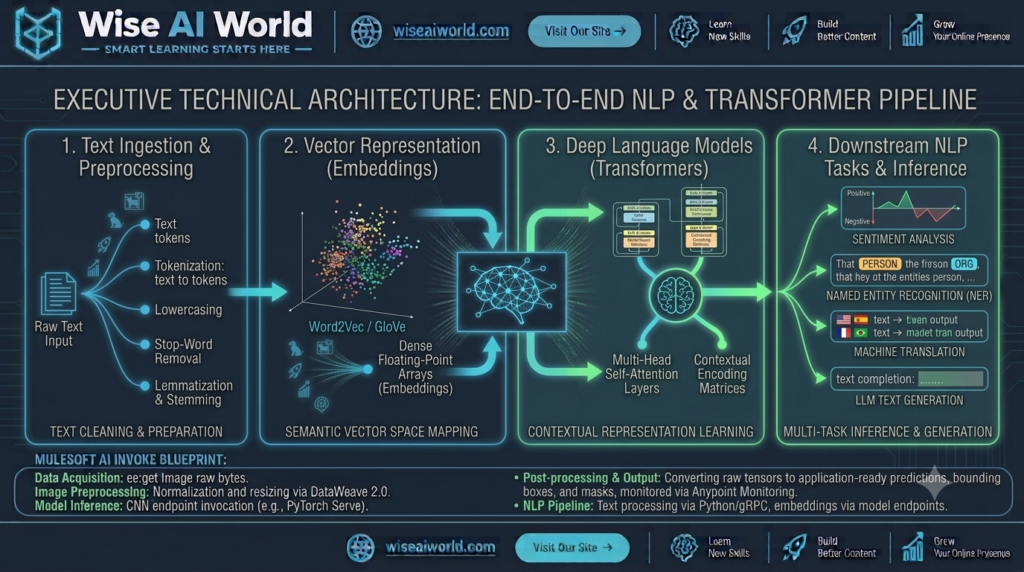
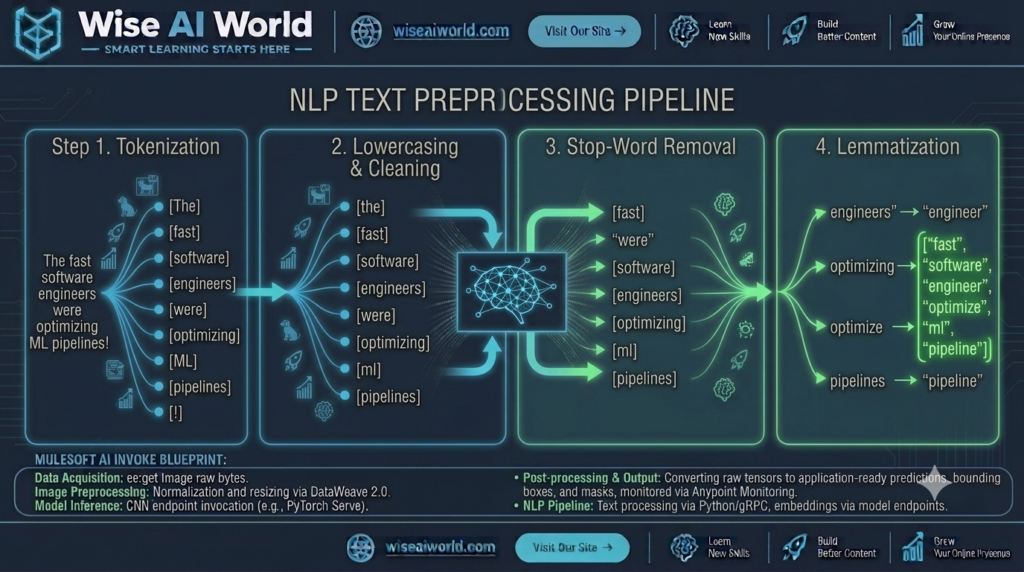
Computers cannot process raw strings directly; they require structured numerical inputs. Before text enters an AI model, it passes through a multi-step **Text Preprocessing Pipeline** to normalize data and eliminate noise.
Step 1: Tokenization
Tokenization is the process of breaking a raw text paragraph into smaller units called tokens. Tokens can be words, subwords, or individual characters.
# Word Tokenization Example
Input Text:  "Artificial Intelligence is changing software development."
Tokens:      ["Artificial", "Intelligence", "is", "changing", "software", "development", "."]
Modern LLMs use **Subword Tokenization** (such as Byte-Pair Encoding or WordPiece) to handle rare words and spelling errors gracefully by splitting unfamiliar words into smaller meaningful roots (e.g., "unbelievable" $\rightarrow$ ["un", "believ", "able"]).
Step 2: Lowercasing and Noise Removal
To prevent models from treating "Python" and "python" as two entirely distinct concepts, all characters are converted to lowercase. Punctuation, special HTML tags, and non-printable characters are stripped out.
Step 3: Stop-Word Removal
Stop words are common grammatical connector words (e.g., “is”, “the”, “at”, “which”) that carry minimal domain-specific semantic value. In classical NLP tasks like keyword extraction or topic modeling, these words are filtered out to reduce noise.
Step 4: Stemming vs. Lemmatization
Words often appear in various inflected forms (e.g., “running”, “runs”, “ran”). Normalization reduces these variations to a baseline root form:
- Stemming: A fast, crude heuristic rule set that chops off word suffixes (e.g.,
"studying"$\rightarrow$"studi"). It often produces non-dictionary words. - Lemmatization: A vocabulary and morphological analysis process that returns the true dictionary root (known as a lemma) (e.g.,
"better"$\rightarrow$"good","running"$\rightarrow$"run").
3. Vector Embeddings: Turning Words Into Numbers
Once text is tokenized and cleaned, tokens must be converted into numerical representations. Early classical techniques used **Bag-of-Words (BoW)** or **TF-IDF (Term Frequency-Inverse Document Frequency)**, which simply counted word frequencies. However, these methods failed to capture context or word meaning.
Modern NLP relies on Word Embeddings (such as Word2Vec, GloVe, or Transformer Embeddings). An embedding maps a word into a high-dimensional mathematical space (often 300 to 1,536 dimensions) where words with similar semantic meanings sit close together geographically.
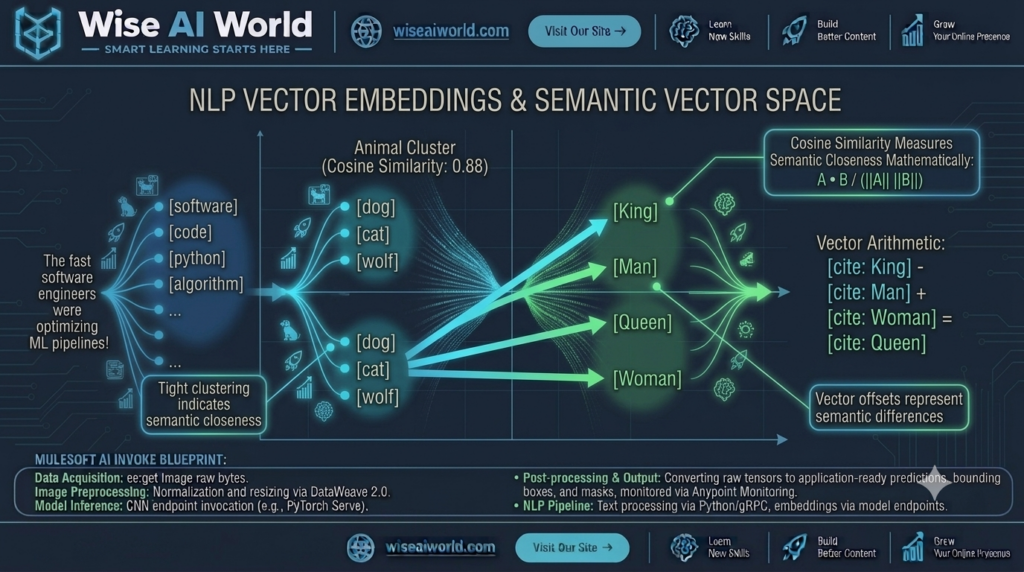
In this vector space, mathematical operations reflect semantic relationships:
Vector("King") - Vector("Man") + Vector("Woman") ≈ Vector("Queen")
Vector("Paris") - Vector("France") + Vector("Germany") ≈ Vector("Berlin")
4. Core Natural Language Processing Tasks
NLP powers a wide range of real-world consumer and enterprise software features:
| NLP Task | What It Does | Example Use Case |
|---|---|---|
| Sentiment Analysis | Classifies emotional tone (Positive, Negative, Neutral) | Monitoring brand reviews, customer support ticket escalation |
| Named Entity Recognition (NER) | Identifies key entities (People, Organizations, Locations, Dates) | Extracting patient names and dosages from clinical notes |
| Machine Translation | Translates text between human languages | Google Translate, cross-border localized eCommerce |
| Text Summarization | Condenses long documents into key bullet points | Legal contract summaries, news digest generation |
| Question Answering (QA) | Extracts or generates precise answers based on reference context | Enterprise RAG Knowledge bases, HR policy bots |
5. Hands-On Python Code: Building an NLP Pipeline using spaCy
Let me demonstrate how to execute a complete NLP pipeline—including tokenization, lemmatization, stop-word filtering, and Named Entity Recognition (NER)—in Python using the industry-standard **spaCy** library.
import spacy

# 1. Load Pretrained English NLP Pipelines
# Run in terminal first: python -m spacy download en_core_web_sm
nlp = spacy.load("en_core_web_sm")

def process_nlp_pipeline(raw_text: str):
    print("=== Raw Input Text ===")
    print(raw_text)

    # 2. Pass text through the spaCy pipeline
    doc = nlp(raw_text)

    # 3. Token Analysis & Lemmatization
    print("\n=== Tokenization & Lemmatization ===")
    print(f"{'Text Token':<15} | {'Lemma Root':<15} | {'POS Tag':<10} | {'Is Stop Word?'}")
    print("-" * 60)
    for token in doc:
        if not token.is_punct: # Skip punctuation
            print(f"{token.text:<15} | {token.lemma_:<15} | {token.pos_:<10} | {token.is_stop}")

    # 4. Named Entity Recognition (NER)
    print("\n=== Named Entity Recognition (NER) ===")
    if doc.ents:
        for ent in doc.ents:
            print(f"Entity Found: {ent.text:<20} | Label: {ent.label_:<12} ({spacy.explain(ent.label_)})")
    else:
        print("No entities detected.")

if __name__ == "__main__":
    sample_text = "Wise AI World launched an enterprise MuleSoft AI tutorial in San Francisco on October 15, 2026!"
    process_nlp_pipeline(sample_text)
Expected Terminal Output:
=== Named Entity Recognition (NER) ===
Entity Found: Wise AI World        | Label: ORG          (Companies, agencies, institutions)
Entity Found: San Francisco        | Label: GPE          (Countries, cities, states)
Entity Found: October 15, 2026     | Label: DATE         (Absolute or relative dates)
6. The Transformer Revolution: From Recurrent Nets to LLMs
Prior to 2017, NLP relied on **Recurrent Neural Networks (RNNs)** and LSTMs. These models processed text sequentially, word-by-word from left to right. Because of this sequential constraint, they struggled with long-range dependencies (forgetting the beginning of a long sentence) and could not be trained efficiently in parallel on GPUs.
In 2017, Google introduced the **Transformer Architecture** in the landmark paper “Attention Is All You Need.” Transformers replaced sequential processing with **Self-Attention mechanisms**.
Self-attention allows a neural network to look at every word in a sentence simultaneously and calculate mathematical attention weights between all words. For example, in the sentence:
“The bank approved the business loan because **it** had strong revenue,”
the self-attention mechanism instantly calculates that “it” refers to the “business”, not the “bank”.
This breakthrough enabled massive parallel GPU training, giving rise to modern Large Language Models (LLMs) capable of understanding and generating human text at scale.
7. Summary & Key Takeaways
Natural Language Processing has evolved from basic dictionary lookup scripts into contextual, deep-learning-driven language architectures that power modern enterprise automation.
| Milestone Era | Dominant Technical Approach | Core Capability |
|---|---|---|
| Classical Era (1990s-2000s) | Rule-based systems, Regex, Bag-of-Words, TF-IDF | Basic keyword search, dictionary lookup |
| Deep Learning Era (2010s) | Word2Vec, Word Embeddings, RNNs, LSTMs | Semantic vector distance, sequential sentiment classification |
| Transformer / LLM Era (2020s+) | Self-Attention, BERT, GPT-4o, Claude 3.5, Llama 3 | Zero-shot reasoning, multi-turn conversational agents, RAG pipelines |

Manish Prakash Dubey is an AI educator and technology writer based in India. He founded WiseAIWorld to make artificial intelligence simple and practical for students, professionals, and beginners. His work focuses on AI basics, machine learning, deep learning, NLP, computer vision, and real-world AI tools.
